 Code
 Data
Point 1What aspects of future states do different representation spaces capture?
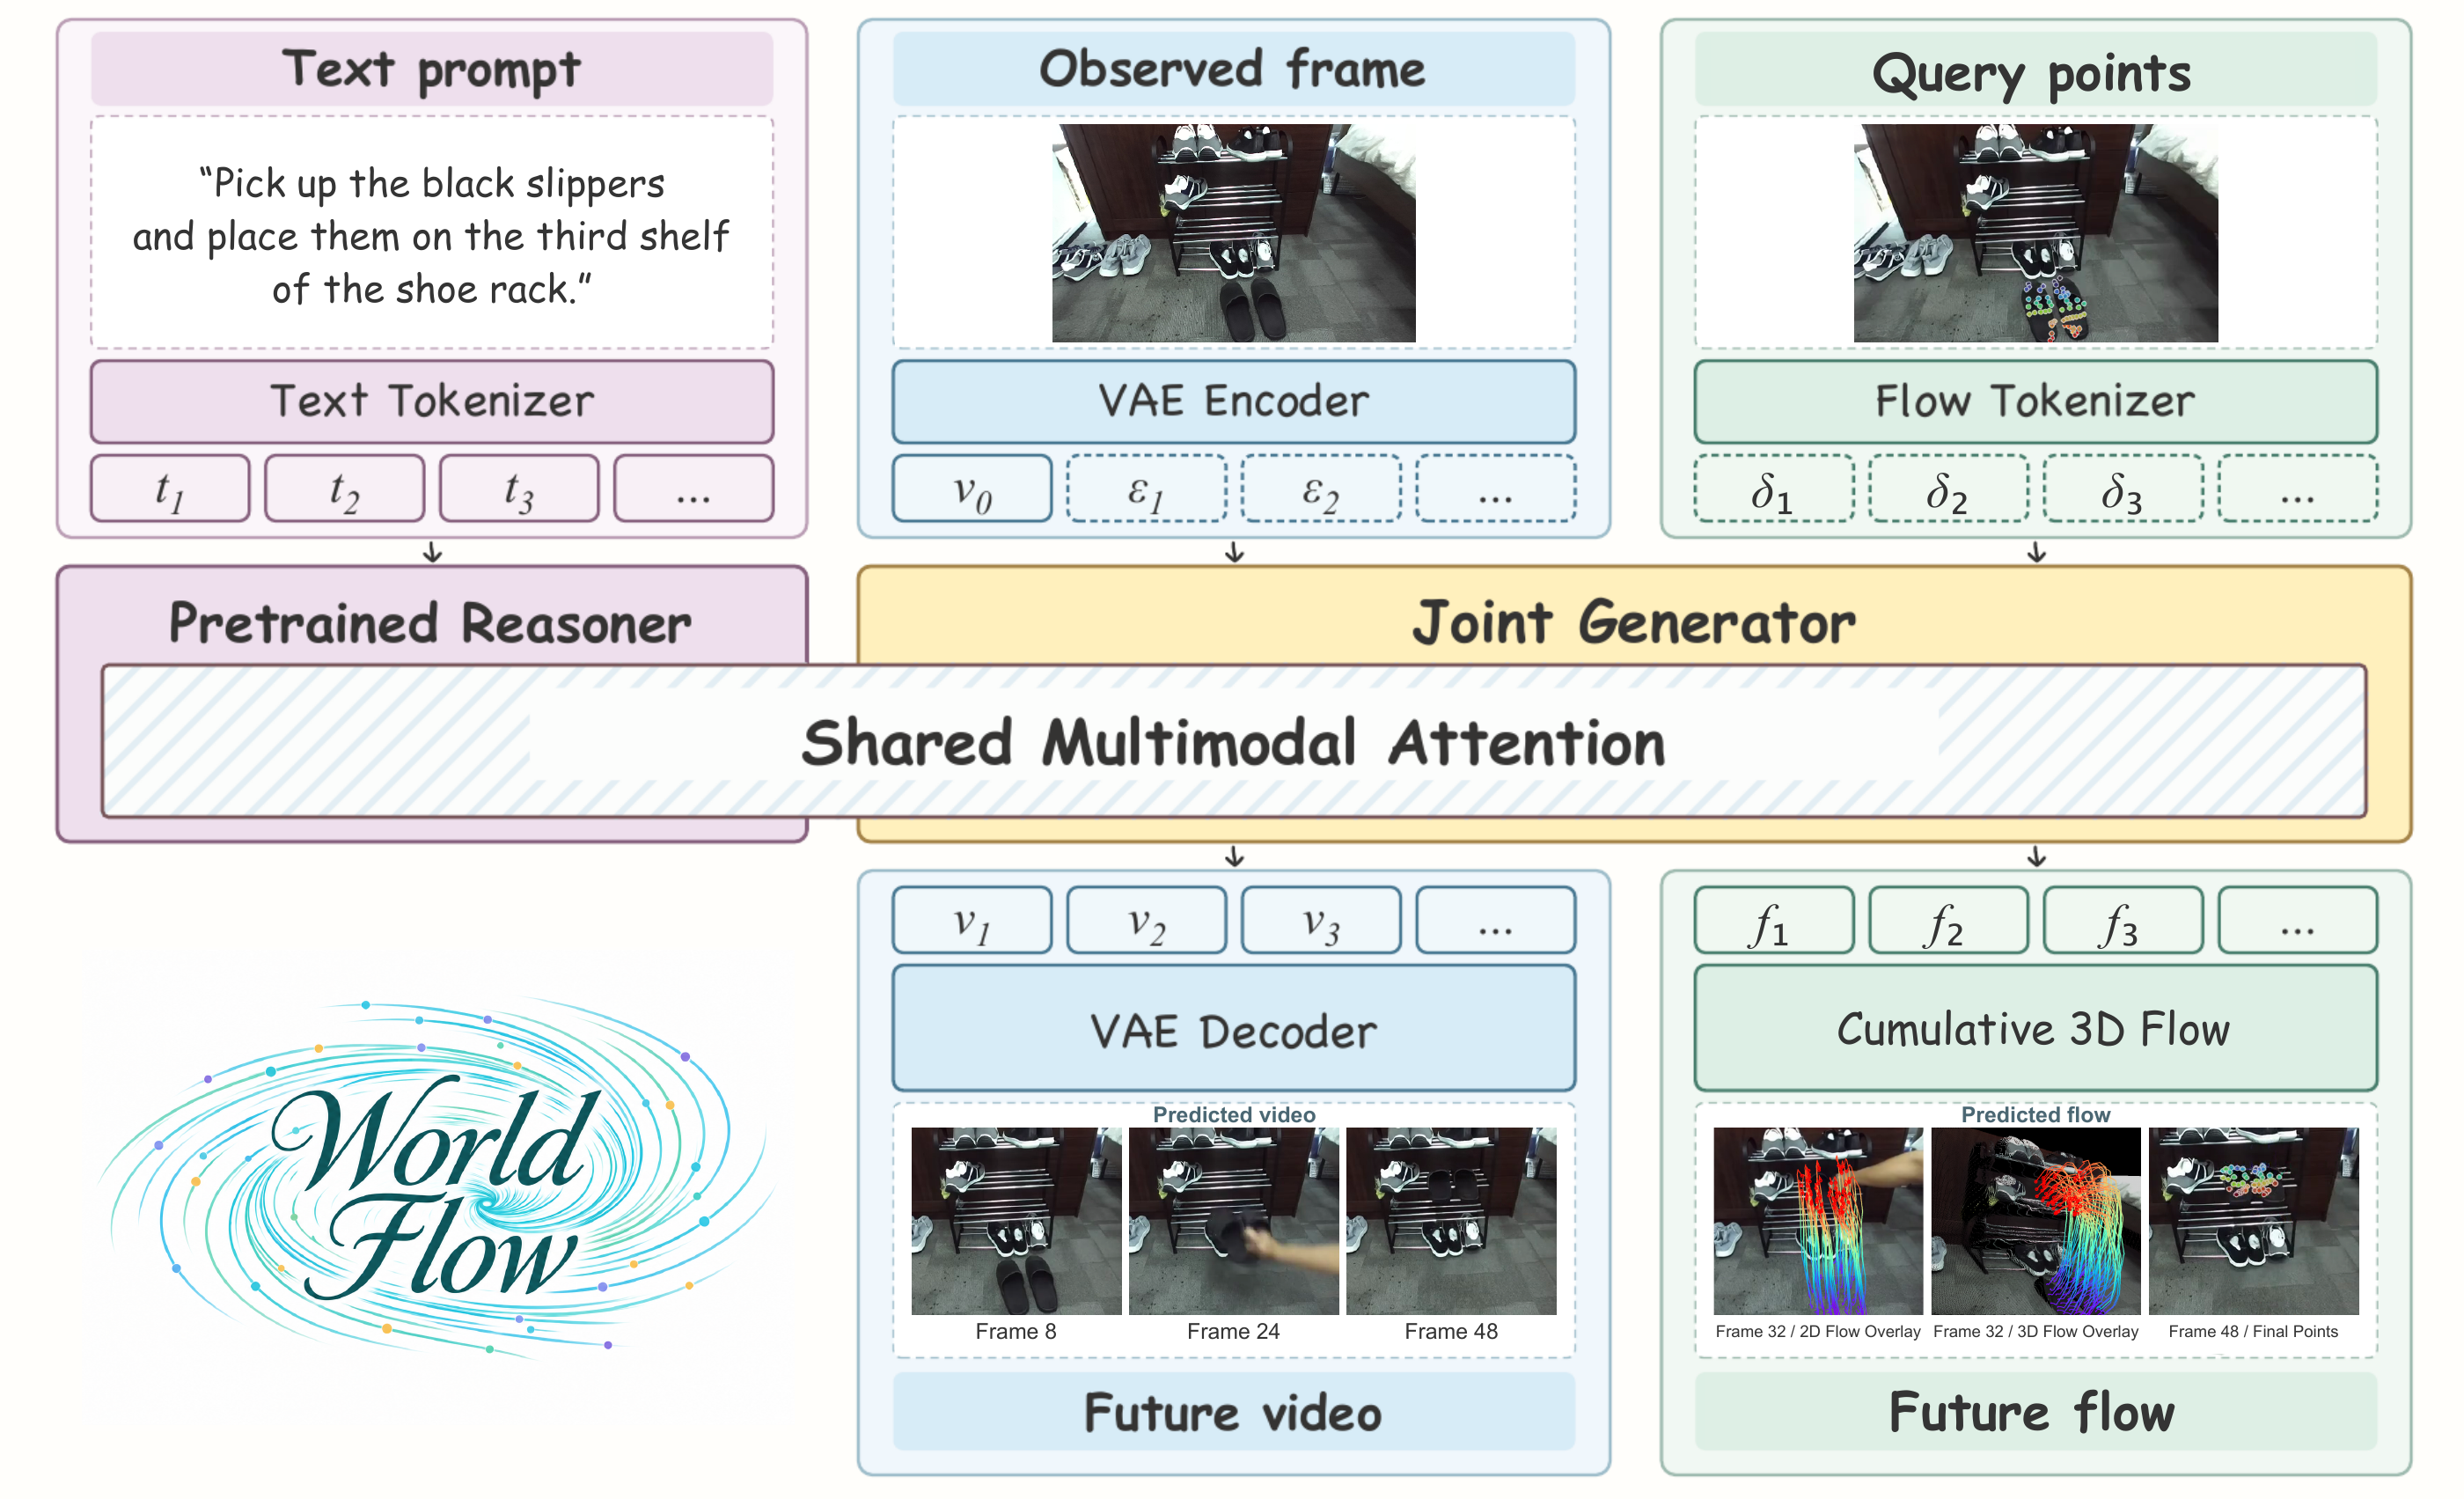
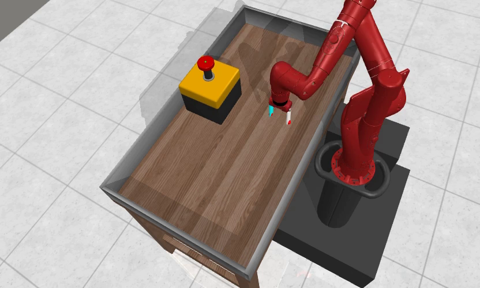
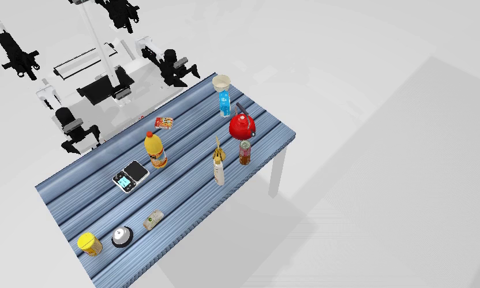
Pixels capture appearance. Actions describe an agent's commands. We choose motion space: explicit 3D motion over time as the core motion prediction space.
Pixel space
What will the world look like?
Future images and video
Limitation: Pixel predictions leave 3D dynamics implicit, requiring additional geometric grounding for manipulation planning and control.
Action space
What should this agent do?
Embodiment-specific commands
Limitation: Embodiment-specific action spaces make models trained on one robot difficult to transfer directly to another.
Motion space (our focus)
How will the world move?
3D flow over time
A shared geometric description of physical change, beyond a particular robot's action interface.
All 3D positions and flow vectors are expressed in the first frame’s camera coordinate system.